x



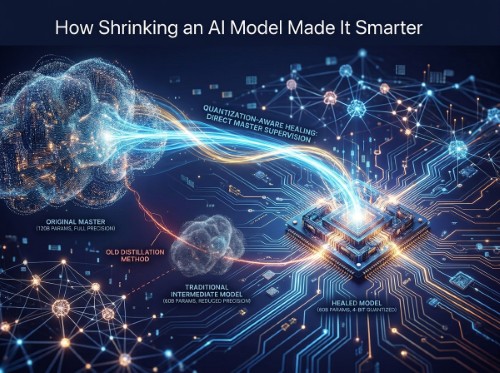
For years, the cardinal rule of artificial intelligence development has been deceptively simple: bigger is better. Larger models packed with hundreds of billions of parameters deliver state-of-the-art reasoning, whilst smaller versions are forced to sacrifice intelligence in exchange for speed, lower costs, and hardware compatibility.
However, groundbreaking research from Multiverse Computing is turning this fundamental assumption on its head. By applying a novel technique known as Quantization-Aware Healing, researchers managed to halve the size of an open-weights AI model and drastically compress its memory footprint—only to find that the smaller, lighter model actually outperformed its full-precision counterpart.
To understand why this discovery is so significant, it helps to examine how large language models (LLMs) operate. An AI model relies on parameters—essentially digital knobs and switches that store the knowledge gained during training. OpenAI's open GPT-OSS model, for example, features a staggering 120 billion parameters.
Running a model of this magnitude requires immense computing power, vast memory reserves, and significant amounts of electricity. To make AI more accessible for everyday applications, developers routinely attempt to compress or "quantise" these systems.
Parameter quantisation reduces the precision of these digital knobs, similar to compressing a crisp 4K video down to a 720p file. Whilst this process drastically cuts down memory requirements, it almost always degrades the AI's intelligence, leaving developers with a weaker, less capable system.
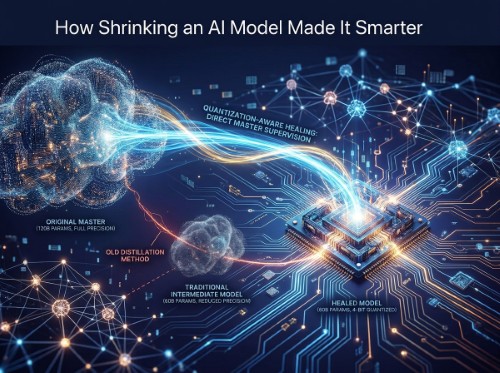
Historically, shrinking an AI model involved a process known as distillation. In standard distillation, a shrunken "student" model learns by attempting to mimic an intermediate "teacher" model—a version that has already been reduced in parameter count but retains higher precision.
The fundamental flaw in this traditional pipeline is akin to making a photocopy of a photocopy. Because the intermediate teacher is already a degraded representation of the original master model, the smaller student ends up learning from a flawed reference point. It effectively imitates a blurry twin, meaning it can rarely overcome the limitations of that intermediate stage.
The team at Multiverse Computing solved this issue by shifting the reference target. Instead of guiding the shrunken model with an intermediate copy, their Quantization-Aware Healing pipeline links the compressed 4-bit, 60-billion-parameter model directly back to the original, uncompressed 120-billion-parameter master AI.
By receiving direct supervision from the full-precision master, the compressed student model retains high-level reasoning and nuanced understanding that would usually be lost during quantisation.
The empirical results were remarkable. When evaluated across nine standard AI benchmark tests, the compressed 60-billion-parameter model outperformed the standard, full-precision 60-billion-parameter version on seven occasions. Whilst the original 120-billion model still holds the overall performance lead, the shrunken version achieved an efficiency-to-accuracy ratio that experts previously considered impossible.
The practical implications of this research are vast. The "healed" model, which has been released under the open-weights name Hypernova-60B on Hugging Face, requires approximately a quarter of the memory and half the parameters of the original 120-billion model.
This dramatic reduction in resource requirements bridges the gap between cloud-bound data centres and local hardware:
Whilst this milestone marks a major step forward for efficient AI, there are key caveats to keep in mind. The tool used to perform the initial parameter reduction remains proprietary, meaning the full compression recipe is not yet entirely open source. Furthermore, the research team focused their initial testing specifically on the GPT-OSS architecture, leaving it to future studies to evaluate how well the technique applies to other major open-source families such as Llama, Qwen, or Mistral.
Nevertheless, the achievement demonstrates that model compression no longer needs to be viewed purely as a compromise. When paired with direct master supervision, quantisation can serve as a powerful tool to refine AI performance, paving the way for lighter, faster, and smarter artificial intelligence on local devices.
Disclaimer: This article is provided for informational purposes only, mistakes may be made, and it's not offered or intended to be used as legal, tax, investment, financial, or any other advice.