x



When a large language model (LLM) hallucinates or outputs an incorrect answer, the immediate assumption among AI developers is that the model suffers from a knowledge deficit. The industry’s standard remedy has long been predictable: scale up parameter counts, ingest millions more web pages, or deploy complex Retrieval-Augmented Generation (RAG) architectures.
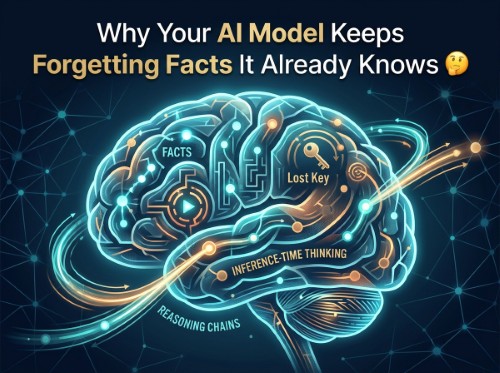
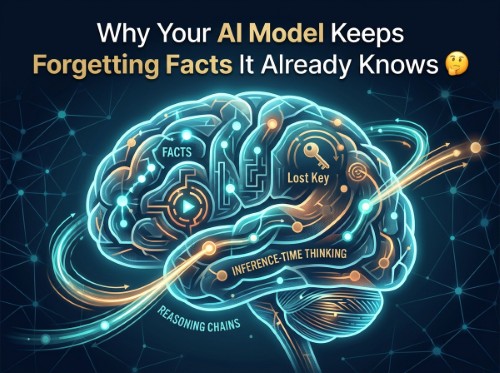
However, groundbreaking research from Google Research and Technion turns this assumption on its head. The study demonstrates that frontier models such as GPT-5 and Gemini-3 already parametrically encode between 95% and 98% of tested facts. The core problem is rarely missing data; rather, it is a failure of memory retrieval during direct text generation.
Crucially, researchers discovered that by simply granting models extra inference-time computation—essentially allowing them time to "think" before generating a final answer—they can recover between 40% and 65% of encoded facts that they initially failed to recall.
To understand why models struggle to surface stored facts, the researchers introduced a framework termed knowledge profiling. Rather than relying on simple pass/fail accuracy scores for isolated prompts, knowledge profiling evaluates a single piece of information across multiple phrasings, contexts, and query directions.
This framework draws a vital distinction between whether a fact is encoded (stored within the model's weights) and whether it is known (reliably accessible across varied prompts).
Based on how an LLM processes information, the study categorises model knowledge into five distinct profiles:
A common misconception in artificial intelligence engineering is that scaling up model parameters automatically solves factual inaccuracies. The study's empirical findings prove that while scaling addresses "empty shelves", it actually exacerbates the "lost keys" dilemma.
When evaluating the Gemma 3 model family, scaling from 1 billion to 27 billion parameters reduced encoding failures dramatically from 85% down to 23%. However, the proportion of recall failures nearly doubled, peaking at 40%.
In essence, expanding model capacity fills the parameters with millions of rare, long-tail facts, but leaves those facts hidden behind inadequate retrieval pathways. As models grow, the bottleneck shifts from data storage to memory access.
Furthermore, models struggle significantly with directional context. For instance, an LLM might effortlessly state that Oasis played their first gig at the Boardwalk club, yet fail completely when asked which band played their first gig at the Boardwalk club. However, when presented with the same reverse question in a multiple-choice format, the model consistently selects the correct answer—proving the information was stored all along.
These insights require a fundamental shift in how software engineers approach LLM factuality and system architecture.
1. Re-evaluate Blanket RAG Deployments
Retrieval-Augmented Generation remains essential for internal proprietary documents or real-time data. However, using RAG as a universal fix for hallucinations introduces unnecessary latency and vector database costs to retrieve information the model already possesses in its memory.
2. Deploy Selective Inference-Time Compute
Allowing models to "think longer" recovers up to 65% of locked facts. However, because only 10% to 20% of user queries actually require extended reasoning, enabling thinking mode globally wastes compute budgets. Systems must implement metacognitive frameworks—such as measuring output uncertainty—to trigger deep reasoning selectively when a direct response is at risk of failing.
3. Implement Generate-Then-Verify Loops
Language models are significantly better at verifying facts than generating them from scratch. Designing pipeline loops where a model generates an initial candidate response and subsequently performs a self-reflection pass can catch subtle mistakes before reaching the end-user.
4. Leverage Query Reformulation and Context Priming
Because recall is heavily dependent on context, prompt framing dictates success. Encouraging models to generate relevant intermediate background details before answering direct questions acts as an effective catalyst for memory retrieval.
The shift from pre-training scale to inference-time optimisation marks a pivotal moment for enterprise software development. Enhancing application reliability no longer strictly requires multi-million-pound training budgets or sprawling infrastructure. By mastering inference-time reasoning and understanding how models retrieve parametric knowledge, engineering teams can unlock immense capability already hidden within frontier LLMs.
Disclaimer: This article is provided for informational purposes only, mistakes may be made, and it's not offered or intended to be used as legal, tax, investment, financial, or any other advice.